indic-reg-bench: a benchmark for Indian regulatory documents
An open benchmark for document understanding on SEBI enforcement orders: five tasks, a harness and a HuggingFace dataset. The harness works. The gold set does not exist yet, so there are no scores, and nothing here is a placeholder number.
Problem
- LLM evaluation suites for regulatory and financial documents are US and EU centric. Indian orders differ structurally: SEBI Act charging provisions, digit grouping where 35,00,000 means 3.5 million, and penalty phrasing that matches no Western template.
- Orders quote the noticee’s own settlement pleas in phrasing identical to the ruling, so the obvious extraction is often wrong.
Approach
- Task design came from 25 real orders and was then re-verified against 2,006 fetched documents.
- Two fields were cut for being regex-solvable. If a regex solves it, it isn’t a task.
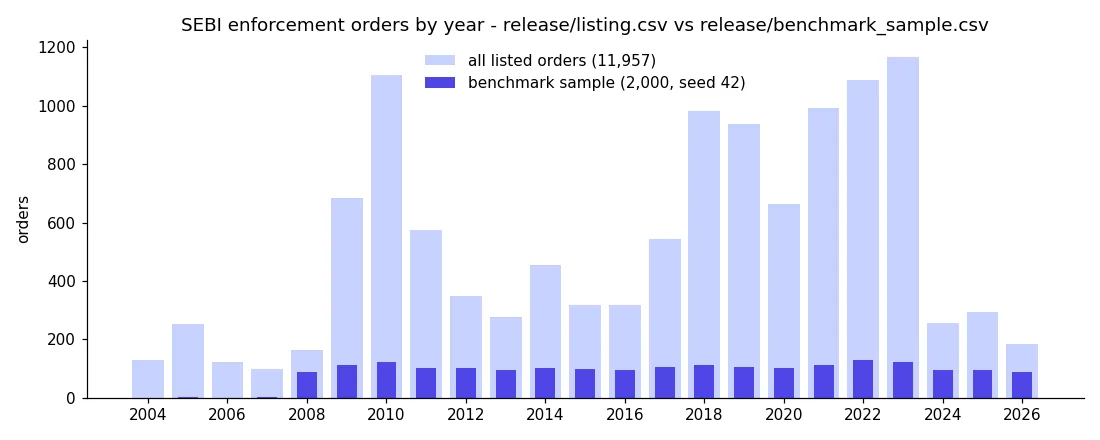
- The split is temporal, cut at 2023, because a regulatory system is built on past orders and run on new ones. Table-scrambled orders are 1.7% of train and 16.1% of test.
- No overall score is produced: the tasks measure different things, and averaging hides which one a system failed. Cost and latency are reported next to accuracy.
- Model-made labels are marked “not a benchmark result”, and the leaderboard stays gold-only.
What failed, and the tradeoffs
- Multi-hop was cut from v1 on the evidence of 25 documents, and that decision was wrong. Across the full 10,827-order listing, 250 entities recur across unrelated matters. It is reinstated for v1.1.
- The gold-set target was 400–600 and is now 200: labelling is restricted to the test split, which holds 408 usable orders.
- The rupee sign extracts as a backtick from a quarter of these PDFs. In 10.4% of them it is the only currency marker, and those documents matched no currency pattern at all: they returned nothing rather than an error.
- One regulator, one document type, English only, single annotator. Agreement is self-agreement across two passes, so it is an upper bound on reliability.
Where it stands
- Gold set: 0 of a target 200 labelled, so baseline scores are blocked and the leaderboard is empty by design.
- 11,957 orders listed on HuggingFace, a 2,000-order sample with seed 42, and a harness with 82 tests passing in CI (2 skipped).
- Measured before any label: a naive first-amount extractor disagrees with the operative paragraph in 48.6% of comparable orders (567 of 1,166), and 18.3% of adjudications impose no monetary penalty.
Stack
- Python
- HuggingFace Datasets
- PDF parsing
- Evaluation
- GitHub Actions